Meta AI Releases Muse Wonder and Wonder Full, Adding Six Reasoning Levels
Reading lead
Meta AI has released Muse Wonder and Muse Wonder Full, describing them as its most capable models. The post says they may be the company’s first models in the “Fable” class, while Artificial Analysis rates Muse Wonder Max as equivalent to GPT-6.1 Sol; this is a reported third-party comparison, not independent validation presented in the article. The author updated the llm-meta-ai plugin and illustrates Muse Wonder’s six reasoning settings—minimal, low, medium, high, xhigh and max—using pelican images, comparing them with outputs from Muse 1.3 and Muse 1.2. The author describes month-by-month releases and material improvement in this specific image-generation example. No benchmark methodology, broader capability evaluation, or detailed model specifications are provided in the material.
Article body
Meta AI release Muse Wonder (and Muse Wonder Full), their new "most capable models". These look like they may be Meta's first Fable class models - Artificial Analysis scores Muse Wonder (Max) as equivalent to GPT-6.1 Sol.
I updated my llm-meta-ai plugin for the new model. Here are pelicans for Muse Wonder for the six reasoning levels: minimal, low, medium, high, xhigh, max. This is the max one:
Image unavailable. Open source image ↗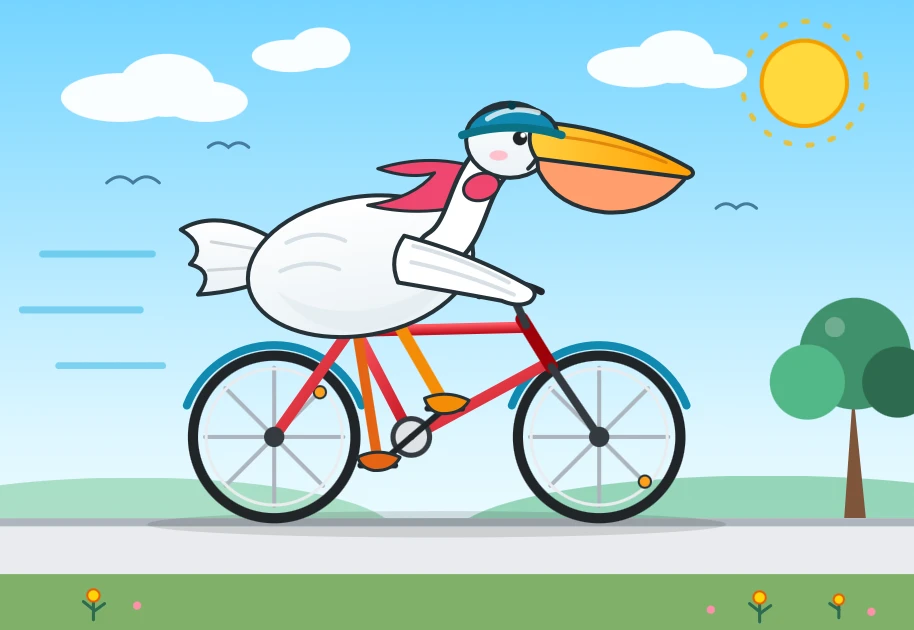
For comparison, here are pelicans for Muse 1.3 (released September 2nd) and Muse 1.2 (released August 5th). Meta AI are putting out a new model a month, and the improvements between each model (at least in terms of drawing pelicans) are material.
Source: ·Simon Willison · 2026-10-12T23:58:46.000Z · Read the original article
Why read this
The concrete news is a new Meta model release with six reasoning settings and an updated plugin; capability claims rely on a narrow pelican example and a cited comparison, without detailed validation.
AI score 56 · View scoring rationale
Two-model scores assess source reading value, not factual accuracy. Check this editorial article against the original.
- gpt-6-luna-2026-09-22 · 54
The concrete news is a new Meta model release with six reasoning settings and an updated plugin; capability claims rely on a narrow pelican example and a cited comparison, without detailed validation.
- deepseek-flash · 58
Covers a claimed Meta model release plus a plugin update, but evidence is limited to a third-party Artificial Analysis score and pelican drawings; no method, specs, pricing, or independent verification.
Analyzed: 2026.10.14 03:50 UTC
Comments & answers 0